2026-09-24 ジョージア工科大学
<関連情報>
- https://news.research.gatech.edu/2026/09/24/new-benchmark-measures-memory-capabilities-vlm-powered-robots
- https://findingdory-benchmark.github.io/
FindingDory:具現化されたエージェントの記憶能力を評価するためのベンチマーク FindingDory: A Benchmark to Evaluate Memory in Embodied Agents
Karmesh Yadav, Yusuf Ali, Gunshi Gupta, Yarin Gal, Zsolt Kira
Abstract
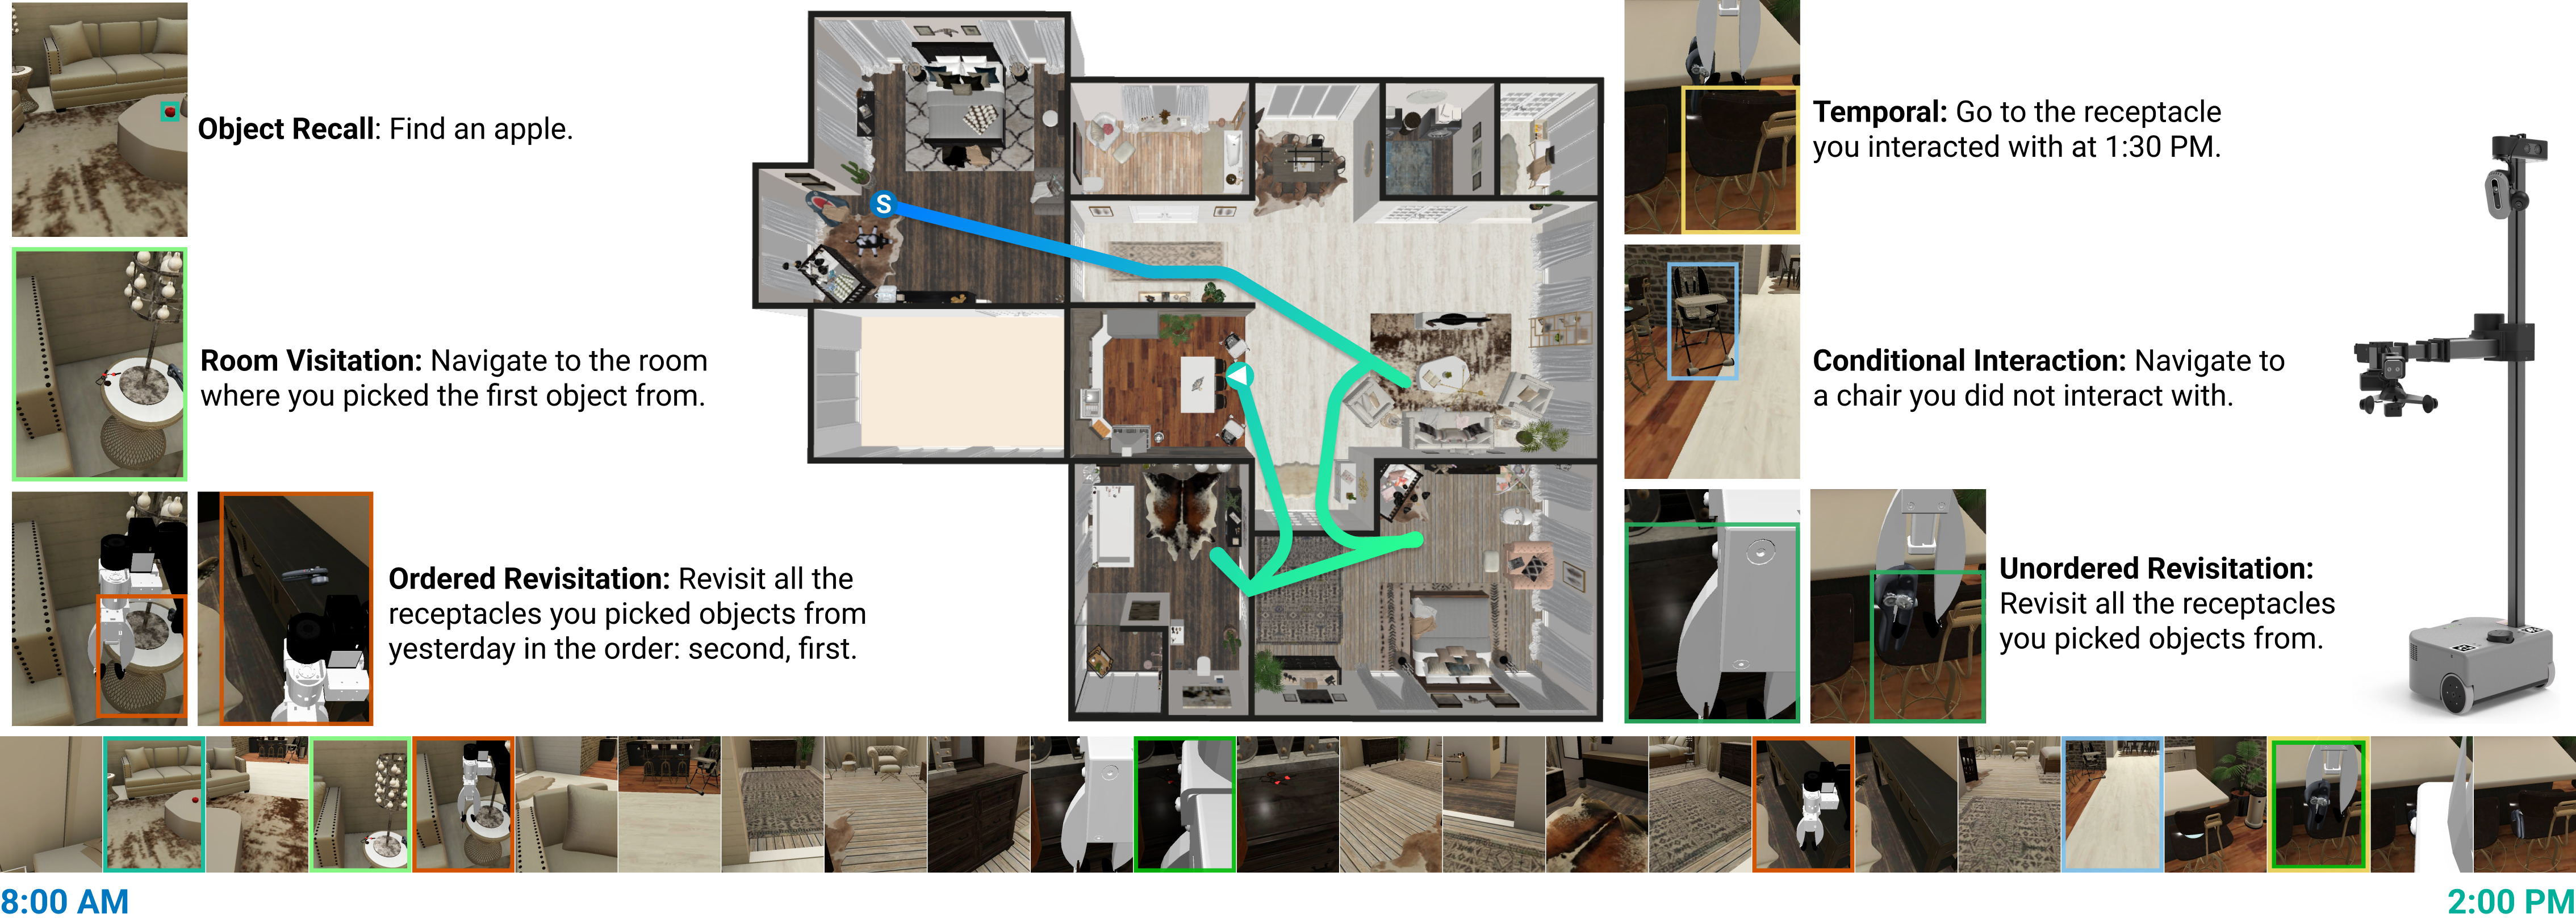
Large vision-language models have recently demonstrated impressive performance in planning and control tasks, driving interest in their application to real-world robotics. However, deploying these models for reasoning in embodied contexts is limited by their ability to incorporate long-term experience collected across multiple days and represented by vast collections of images. Current VLMs typically struggle to process more than a few hundred images concurrently, highlighting the need for more efficient mechanisms to handle long-term memory in embodied settings. To effectively evaluate these models for long-horizon control, a benchmark must specifically target scenarios where memory is crucial for success. Existing long-video QA benchmarks overlook embodied challenges like object manipulation and navigation, which demand low-level skills and fine-grained reasoning over past interactions. Moreover, effective memory integration in embodied agents involves both recalling relevant historical information and executing actions based on that information, making it essential to study these aspects together rather than in isolation. In this work, we introduce a new benchmark for long-range embodied tasks in the Habitat simulator. This benchmark evaluates memory-based capabilities across 60 tasks requiring sustained engagement and contextual awareness in an environment. The tasks can also be procedurally extended to longer and more challenging versions, enabling scalable evaluation of memory and reasoning. We also present baselines that integrate state-of-the-art VLMs with low level navigation policies, assessing their performance on these memory-intensive tasks and highlight areas for improvement.