2026-11-11 東北大学
東北大学電気通信研究所の朱逸飛大学院生、北村喜文教授らと香港大学の幸村琢教授らの共同研究グループは、音声発話から3Dデジタルヒューマンの表情、手指、全身動作を一体的に生成するAI「DynaConTalk」を開発した。従来の音声連動型アニメーションでは、長時間の発話に伴う動作の不自然な揺れや、単調な身振りが課題となっていた。本技術では、人間の動きを時間的な速さに応じて、姿勢変化、身振り、手指や表情の細かな動きなどに分解して学習するウェーブレット制約付き拡散モデルを採用した。さらに、発話のリズム、声の特徴、言葉の意味を状況に応じて使い分けることで、音声と動作の自然な同期を実現した。公開データセットBEAT2とSHOWを用いた評価では、生成動作の分布を示すFGDを従来の最良値からそれぞれ約51%、約29%改善した。また、30人による評価でも、自然さ、発話内容との一致、同期性、多様性で従来手法を上回った。姿勢や参考動作による生成制御も可能であり、対話型AI、バーチャルアバター、遠隔コミュニケーション、デジタルエンターテインメントなどへの応用が期待される。
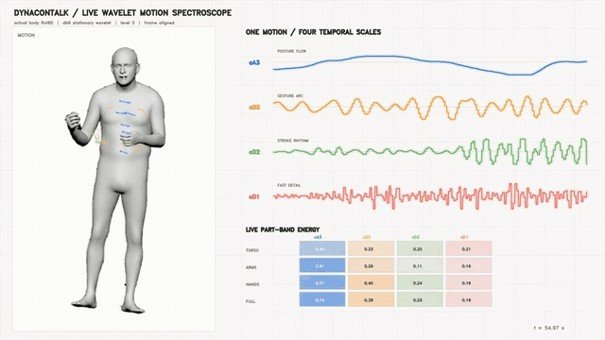
図1. 生成動作のウェーブレット分解の例。左は3Dデジタルヒューマンの動作、右上は低速から高速までの4つの時間周波数成分(姿勢・身振り・ストローク・細部)、右下は部位ごとの帯域エネルギーを示す。
<関連情報>
DynaConTalk:ウェーブレット制約付き拡散モデルによる長時間・制御可能な音声連動型3D全身動作生成(DynaConTalk: Wavelet-Constrained Diffusion for Long-Form and Controllable Holistic Co-Speech 3D Motion)
Yifei Zhu, Yangyang Cai, Mingyi Shi, Miao Cheng, Lin Gu, Taku Komura, Yoshifumi Kitamura
ACM Transactions on Graphics, 45(6), Article 194 2026-11-09
DOI: 10.1145/3842553
Tii-summary
本研究では、音声に同期して人物の表情、手指、全身の動きを自然に生成するAI技術「DynaConTalk」を開発した。従来の音声連動型アニメーションでは、身体の姿勢や身振り、手指・表情の細かな動きが一体的に処理されるため、動作が平均化され、表現力が低下する問題があった。研究グループは、定常ウェーブレット変換(SWT)を用いて動作を時間的な周波数帯に分解し、姿勢変化、身振り、細かな表情・手指の動きを個別に学習する拡散モデルを構築した。さらに、音声のリズム、音響特徴、発話内容、話者の個性を動作の状態や生成段階に応じて統合する動的制御機構を導入した。過去の動作履歴や指定した姿勢を生成過程に組み込むことで、長時間の動作生成や部分的な修正、参照動作に基づく制御にも対応する。対話型アバターやデジタルヒューマンなどにおいて、自然で表現力豊かな音声連動型3Dアニメーションの実現に貢献する技術である。
This study presents DynaConTalk, a wavelet-constrained diffusion framework for generating natural, long-form 3D human motion synchronized with speech. The system produces coordinated body movements, hand gestures, and facial expressions while addressing the over-smoothing and loss of expressive detail often found in conventional co-speech animation. It performs diffusion in stationary wavelet transform (SWT) space, separating motion into temporally aligned frequency bands representing coarse posture changes, intermediate gesture dynamics, and fine expressive details. A dynamic conditioning mechanism integrates speech rhythm, acoustic features, linguistic information, and speaker identity according to the evolving motion state and diffusion stage. The framework also introduces matched-noise constraint injection, enabling seamless long-form continuation, localized keypose editing, and reference-guided motion control within a unified generation process. This approach offers a versatile foundation for expressive digital humans, interactive avatars, and speech-driven virtual agents.
This study presents DynaConTalk, a wavelet-constrained diffusion framework for generating natural, long-form 3D human motion synchronized with speech. The system produces coordinated body movements, hand gestures, and facial expressions while addressing the over-smoothing and loss of expressive detail often found in conventional co-speech animation. It performs diffusion in stationary wavelet transform (SWT) space, separating motion into temporally aligned frequency bands representing coarse posture changes, intermediate gesture dynamics, and fine expressive details. A dynamic conditioning mechanism integrates speech rhythm, acoustic features, linguistic information, and speaker identity according to the evolving motion state and diffusion stage. The framework also introduces matched-noise constraint injection, enabling seamless long-form continuation, localized keypose editing, and reference-guided motion control within a unified generation process. This approach offers a versatile foundation for expressive digital humans, interactive avatars, and speech-driven virtual agents.
原著論文:ACM Digital Library